Hacker News, Re-ranked by a Sentence
Type what you feel like reading and the front page reorders itself in about a second. Built on Jev, a model that judges instead of writes.
The Hacker News front page is one list in one order, and it's the same order for everyone. I built a version where you type a sentence and the top 500 stories reorder around it. "Space, with real numbers in it." "Someone admitting they were wrong." "A founder explaining why it failed." The list re-ranks in about a second, and it's the real front page, refreshed every five minutes.
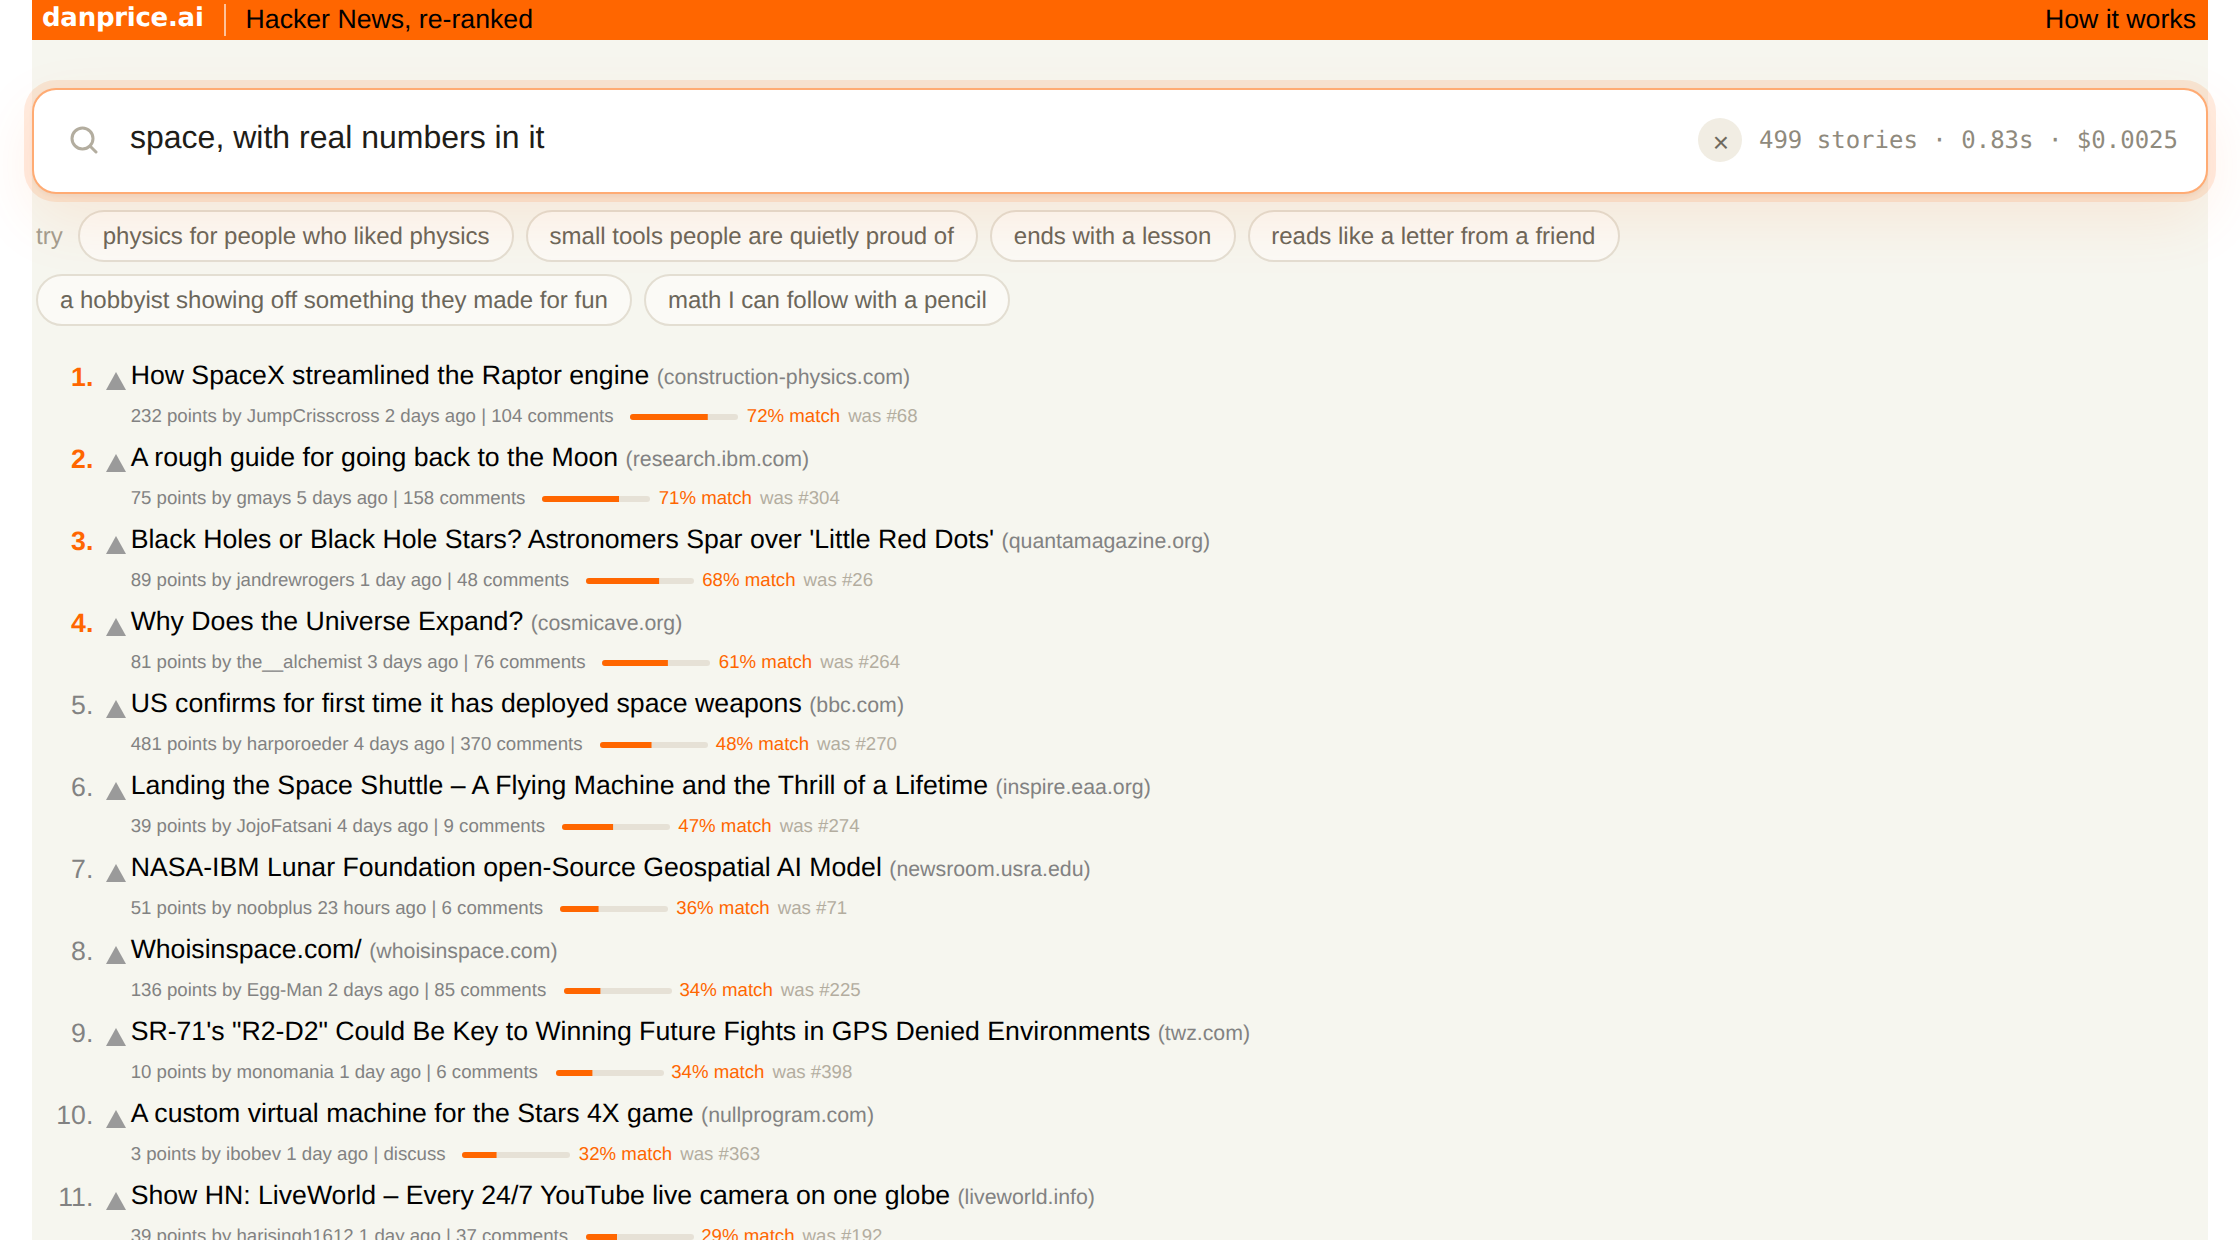
The interesting part is what's underneath. There's no search index, no embeddings, no fine-tuning, and no prompt to speak of. Every re-rank sends all 500 stories to Jev, a model from TypeSafe, with one question each: how well does this story match what the reader asked for? Jev doesn't write anything back. It only answers questions, and it answers all 500 of them in parallel, in under a second, for about a fifth of a cent. The bar at the top of the page shows the real time and cost of your last re-rank, because I didn't believe the numbers either.
Judging a story by its headline turned out to be the weak spot. "Someone admitting they were wrong" needs to know what the article actually says, and whether the author is the one admitting it. So in the background each linked article is read once and boiled down to a few paragraphs: what it argues, and where the author is coming from. Jev gets the summary alongside the title and judges the story on its content and its stance. Paywalls and bot walls still get judged on the title alone.
One thing I had to spell out. Asked for "no AI", Jev initially surfaced the essays arguing against AI, which is a reasonable reading of the request and not the one anyone means. A short guide in the question now says that a negative request excludes the whole topic, with a few examples, and that fixed it.
What I like about this is how little there is to it. The re-ranker is a few hundred lines of Python and one question. Most of the things I'd normally reach for to build a recommender, a vector store, a training loop, a relevance model, weren't needed, because the model is fast and cheap enough to just ask it about everything, every time.